A server for home lab — boring hardware, safer reboots
Build around ECC, remote management, separated storage, and replaceable GPU compute—then prove recovery…
The short version
- A reliable home lab server prioritizes ECC, remote management, PCIe expansion, and separation between storage and replaceable compute.
- The tested 120-billion-parameter model generated 51 tokens per second while remaining fully resident in 128GB unified memory.
- Readers should choose hardware by recovery requirements and measured workloads, not GPU prestige or benchmark-leading specifications.
The most expensive home lab is the one you’re scared to reboot. I once left a server running for weeks because I couldn’t remember whether its display output worked, and reaching it required an archaeological dig through furniture.
TrueNAS describes its new Proxmox plugin with a wonderfully dangerous promise:
You click the button. TrueNAS builds the disks.
Yes, please. I love buttons. Every magical button eventually produces a log file at 2 a.m.
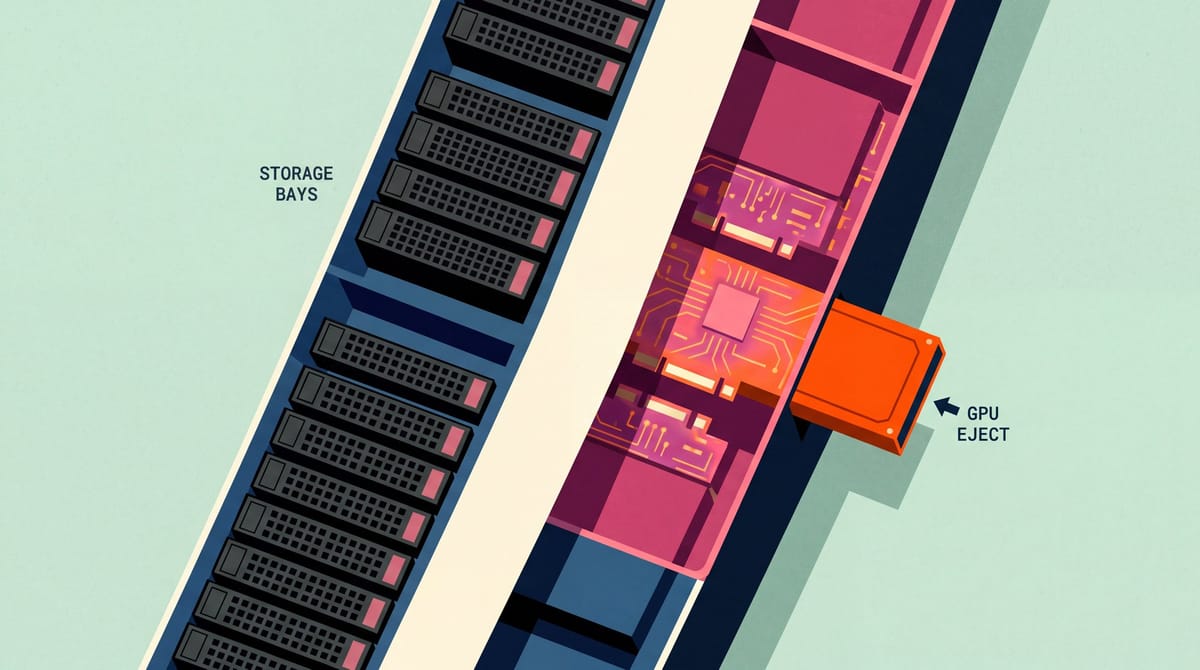
My ideal home lab server has ECC memory, remote management, plenty of PCIe expansion, and a hard boundary between storage and replaceable compute. GPUs come and go. Containers get rebuilt. Family photos shouldn’t depend on whether an NVIDIA driver woke up spicy.
Start with the blast radius
I start with one question: what disappears when this box dies? A tower running the NAS, hypervisor, router, databases, and AI stack creates a magnificently large failure domain. One box can still make sense, especially if the alternative is explaining another rack purchase to your partner, but I organize datasets and backups so compute can move later. Important files get an independent copy. Experimental containers get isolated storage. The GPU can leave without taking the NAS. That separation prevents more pain than another benchmark-winning CPU.
Splitting Proxmox and TrueNAS makes the boundary obvious. When Proxmox requests a VM disk, the TrueNAS plugin creates an automated ZFS zvol on the storage machine, then publishes it as an iSCSI LUN or NVMe/TCP namespace. The VM’s blocks cross the storage network. Proxmox provisions disks and takes native OpenZFS snapshots through its usual interface; resizing, migration, and deletion use the same workflow. Previously, every storage change meant creating a zvol, then adding an iSCSI extent and LUN mapping. That gets old around VM number two. NFS snapshots use QEMU copy-on-write files and can block a VM, while plugin-backed disks expose native storage snapshots. Imports and backups still run host-side; according to TrueNAS, so do clones and moves.
File storage needs its own lane. Proxmox can’t put ISO images, vzdumps, or ordinary backup files on iSCSI or NVMe storage, so I still need an NFS or SMB export, possibly from the same TrueNAS pool. One pool can expose several interfaces because a running database disk and a directory of installer images have very different personalities at dinner.
The official deployment needs TrueNAS 25.10 or newer; earlier releases lack the versioned JSON-RPC WebSocket API required by the plugin. iSCSI works with Proxmox VE 8.x, while NVMe/TCP requires PVE 9.x. A transport choice can therefore trigger a cluster upgrade, so I’d start with iSCSI unless NVMe/TCP solves a measured problem.
Networking is part of that choice. I treat 2.5GbE as the floor and consider 10GbE when VM disks, model files, or backups regularly cross machines. ServeTheHome reviewed Ubiquiti’s rackmount USW-Pro-XG-10-PoE at around $700, with ten copper ports and two SFP+ links. Most beginners can keep their credit cards holstered. QNAP’s M2130 offers a better topology to copy: several slower client ports feeding fewer fast uplinks for storage and compute.
Raspberry Pis get the chores
I like Raspberry Pis for DNS, monitoring, and disposable containers I can reimage before lunch. That’s the emotional commitment these jobs deserve. Shared storage and VM disks need better expansion, remote recovery with a dead operating system, and visible memory-error reporting.
ECC provides that visibility when the entire platform supports it. Side-band ECC stores check bits so the memory controller can verify data moving between the DIMM and CPU. A common SECDED setup corrects one-bit errors, detects two-bit errors, and exposes counters to the operating system. That warning lets me replace a degrading DIMM before corruption becomes a mystery novel. DDR5 on-die correction works inside the memory chip and remains invisible to the OS, so it lacks equivalent system-level reporting. The CPU, motherboard firmware, DIMMs, and operating system must all support ECC. An online listing containing “ECC” proves about as much as an Italian restaurant with a Vespa outside.
An ECC guide citing Google fleet data found that roughly three-quarters of uncorrectable errors followed a correctable error during the same or previous month. Those servers came from the DDR1 and DDR2 era, so I wouldn’t apply that rate to a modern home lab. The early warning remains the lesson.
I also want a BMC. It stays reachable independently of the main operating system, letting me inspect firmware, open a remote console, or power-cycle a frozen host. ServeTheHome’s ASUS Pro WS W890E-SAGE SE review shows the luxurious version: an ASPEED BMC, dual 10GbE, eight RDIMM slots, and seven physical PCIe slots. With a capable enough Xeon, six slots run at full x16 width and the last at x8. The board is enormous and expensive, but it shows what I count: electrical lanes and card spacing first, then NICs and remote-console access.
Tiny hybrid boxes demand harsher compromises. TechRadar reported that Morefine’s roughly sixteen-liter MNAS-X1 fits four drives beside a full-length, three-slot GPU. Its RTX 5070 drew about 250 watts and averaged 80°C during a short stress run. That can’t predict long-term reliability, but it shows where heat goes when disks and GPU compute share a shoebox: everywhere, molto democratico.
The RTX 5090 can wait
An RTX 5090 makes sense when a specific model and context window need its memory, or measured request volume requires its throughput. Until then, I keep my money and test existing hardware.
Model weights consume memory first. Quantization shrinks them; context and runtime overhead consume more capacity. A fully resident model avoids repeatedly pulling weights across a slower connection during generation. If weights spill into system memory, each inference step can stall on data movement and throughput can collapse. Concurrent requests add working memory, forcing the runtime to schedule competing sequences. A larger GPU pays off when residency or sustained demand becomes the constraint. Before shopping, I write down the target model and acceptable latency, then check expected usage, cooling, slot width, and which PCIe device gets evicted.
On August 25, 2026, I tested local models on an M3 Max with 128GB of unified memory.
The fully resident gpt-oss:20b generated 74 tokens per second and processed prompts at 756 tokens per second. Its first token arrived in about four seconds, and the MXFP4 model has roughly 21 billion parameters.
The larger gpt-oss:120b generated 51 tokens per second and processed prompts at 215 tokens per second. Its first token took about six seconds; all 117 billion MXFP4 parameters stayed in memory.
Those results changed how I choose the best local LLM. The smaller model felt faster; the larger bought capability with clear latency. I choose the cheapest model that passes a private test set built from my coding tasks, documents, or agent calls. Leaderboards rarely include my weird invoice format or the moment ComfyUI eats the GPU.
That happened here. With ComfyUI occupying the RTX 5060 Ti’s 16GB of memory, Ollama had only 150MB of VRAM, forcing the 20B language model entirely onto the CPU. A GPU inside the machine may already have a full-time job.
Unified memory becomes compelling when capacity matters more than peak speed. Tom’s Hardware reported Minisforum systems announced with up to 192GB, including as much as 160GB assignable to graphics. Pricing and availability remained undisclosed.
TechRadar tested GMKtec’s shipping EVO-X3 with 128GB of soldered memory and up to 96GB available to its integrated GPU. The review found unfinished software and a 2.5GbE network bottleneck. PC Watch tried another route: connecting an external RTX 3090 over OCuLink and running a quantized Qwen model larger than 100GB at about 21 tokens per second after tuning. Transfers saturated the narrow external link.
AMD’s planned Threadripper Halo Station takes this architecture into glorious lunacy: a 96-core CPU with two professional accelerators carrying 144GB each. It targets 2027, with no announced price. I admire it like a Lamborghini parked outside an Esselunga.
Ollama vs vLLM ends at the recovery test
For Ollama vs vLLM, I use Ollama for simple single-user work and vLLM when several clients need sustained API throughput. A self-hosted AI agent sits above either runtime in an isolated VM or container, with one working directory and task-scoped credentials.
The runtime loads the model, allocates memory, schedules requests, and exposes an API. Simplicity wins for occasional single-user traffic because the accelerator often sits idle. Shared traffic brings different prompt lengths, while token-by-token generation leaves scheduling gaps between sequences. vLLM’s batching-oriented design combines compatible work to keep more of the accelerator occupied. Higher aggregate throughput can still leave one request queued. I benchmark end-to-end latency at expected concurrency with the exact model I’ll serve. Available research offers no direct comparative benchmark, so universal Ollama-versus-vLLM verdicts remain vibes seasoned with YAML.
My agent gets narrowly mounted data, limited network access, and zero authority over the hypervisor or NAS. Snapshots allow quick rollback after a bad change, but share the storage failure domain and can’t replace independent backups. Local execution keeps data away from external providers; strict permissions keep the agent away from my infrastructure’s throat.
Recovery improves when configuration leaves my head. The official TrueNAS Terraform provider manages 85 resources, 84 with matching data sources. It requires Terraform 1.11 or newer because older releases lack write-only secret attributes for passwords and CHAP credentials.
Given an API-key owner name, the provider asks TrueNAS which authentication methods the server supports. It uses SCRAM-SHA-512 when available and otherwise falls back to API-key login. Terraform compares declared configuration with recorded state, exposing drift. On replacement hardware, that state can restore datasets, shares, permissions, snapshot tasks, and replication settings. I still need a tested backup because configuration code can’t recreate missing data. It does remove the ritual of clicking through a half-remembered setup while everyone asks when Jellyfin returns.
For now, I’m keeping the Proxmox plugin away from irreplaceable workloads. TrueNAS calls it an Early Adopter release and says Enterprise support remains under validation. GitHub user lucasblack29 reported that stopped HA-managed VMs couldn’t restart because HA Manager rejected the custom storage type on a three-node Proxmox 9.2.11 cluster running plugin version 2.1.23-beta2. A later pull request added service restarts to load that type, but available evidence doesn’t confirm the fix has reached every installation path.
That report needs a fair reading. It came from one beta configuration and doesn’t prove every cluster will fail. But it hits the exact moment storage integration matters most: a stopped VM asking HA Manager to revive it. Nobody has confirmed the failure is fixed in a released installation path. Published home-lab comparisons with NFS, manual iSCSI, and NVMe/TCP are also missing. We still need results for storage-network loss, a TrueNAS reboot, and a Proxmox-node restart. Enterprise validation has no published completion date.
My next server earns its place when I can replace the motherboard, reapply configuration, reconnect storage, and watch the first VM boot before the espresso gets cold. Until then, an RTX 5090 is very expensive mood lighting.
Frequently asked questions
What should a reliable server for home lab use include?
A reliable server for home lab use combines ECC memory, independent remote management, enough PCIe expansion, and a clear separation between storage and replaceable compute. Important files also need an independent backup, because snapshots and configuration code cannot recover data lost with the storage system.
Is an RTX 5090 worth buying for a home lab?
An RTX 5090 is worthwhile when a specific model and context window require its memory, or measured request volume requires its throughput. Existing hardware should be tested first, including model residency, latency, cooling, slot width, power use, and the PCIe device the GPU would displace.
Should a local AI server use Ollama or vLLM?
Ollama suits simple, occasional single-user workloads. vLLM suits several clients needing sustained API throughput because its batching-oriented scheduler combines compatible work and keeps more of the accelerator occupied. The correct choice depends on end-to-end latency measured at expected concurrency with the exact model being served.
Sources
- The official TrueNAS Terraform provider, now available for deployment!
- TrueNAS Proxmox Plugin - Ready for Community, Under Testing for Enterprise
- TrueNAS Cinder driver for OpenStack; we’d like you to break it!
- ASUS Pro WS W890E-SAGE SE Motherboard Review
- Ubiquiti UniFi USW-Pro-XG-10-PoE Review A Sweet 10GbE Switch
- QNAP QSW-M2130 2.5GbE and 10GbE Switches Shown